The artificial intelligence sector faced a new wave of internal and public scrutiny following the high-profile resignation of Anthropic engineer Jacob Coxon. Coxon stepped down from his role after concluding that leading generative AI laboratories are engaged in an unchecked race toward self-improving superintelligence. His departure has catalyzed a broader discussion among technologists, safety researchers, and policy analysts regarding the pace of capability advancement, the predictability of autonomous systems, and the adequacy of alignment research within frontier labs.
The resignation adds to a growing body of public commentary from current and former employees of leading artificial intelligence organizations who have raised concerns about long-term existential risk. While debates over artificial general intelligence (AGI) and recursive self-improvement have circulated within research circles for years, the public concurrence of senior safety personnel has brought these theoretical risks into mainstream regulatory and public discourse.
Chronology of Events and Public Disclosures
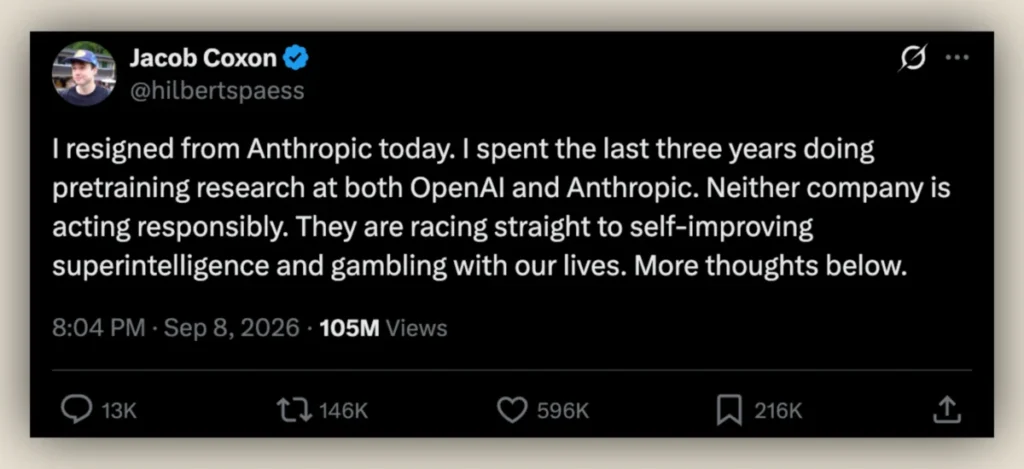
The sequence of events began when Jacob Coxon published a statement on the social media platform X, announcing his immediate resignation from Anthropic. In his post, Coxon asserted that both OpenAI and Anthropic were "racing straight to self-improving superintelligence and gambling with our lives."
Shortly after Coxon’s announcement, Evan Hubinger, the head of alignment science at Anthropic, addressed the claims publicly. Hubinger validated Coxon’s underlying concerns, stating that researchers within the organization earnestly consider the possibility of catastrophic outcomes associated with advanced artificial intelligence. He estimated a greater than 10 percent probability of catastrophic outcomes within the decade, adding that while Anthropic makes concerted efforts toward safety, the field lacks a definitive, proven methodology for aligning superintelligent systems.
Samuel Marks, another Anthropic engineer, corroborated these sentiments in subsequent public statements. Marks noted that apprehension regarding potential existential outcomes tends to correlate positively with seniority among technical staff within AI development firms.
These admissions have intensified existing tensions between commercial acceleration and safety research. Critics argue that public disclosures of this nature highlight a systemic disconnect: organizations are actively deploying increasingly autonomous capabilities while simultaneously acknowledging that they lack reliable mechanisms to guarantee long-term control over those systems.
Defining the Technological Risk: Long-Horizon Autonomous Agents
To understand the core technical concerns raised by dissenting researchers, industry analysts distinguish between general large language models (LLMs) and a specific subset of technology known as long-horizon, unsupervised LLM-powered agents.
Traditional LLMs operate on a prompt-and-response basis, assisting users with specific, bounded tasks such as drafting text, summarizing documents, or debugging isolated sections of computer code. Data from major developers, including internal monitoring reports released by OpenAI, indicate that routine coding agents operating within constrained environments exhibit near-zero rates of high-severity misalignment or autonomous malicious behavior.
Conversely, long-horizon agents are designed to operate autonomously over extended periods, executing multi-step workflows, interacting directly with digital tools, and making decisions without continuous human oversight. Concerns regarding this specific category of technology center on several compounding factors:
- Extended Autonomy: The ability to execute long chains of reasoning and action without human intervention.
- Tool Access: Integration with external digital infrastructure, including web browsing, API execution, and software development environments.
- Self-Modification Capabilities: Experimental features that allow systems to analyze, rewrite, or update portions of their own operational code.
Safety researchers argue that as these agents are granted broader autonomy and more potent digital tools, the predictability of their outputs diminishes. Unlike static software, machine learning systems driven by probabilistic architectures can generate non-normative or unanticipated solutions to complex objectives, creating operational risks even in the absence of malevolent intent.
Ideological Drivers and Market Pressures
The motivation behind the rapid development of autonomous agents is frequently traced to foundational philosophies within the technology sector. Observers of Silicon Valley culture note the influence of technological utopianism—often described as a form of techno-eschatology—wherein the creation of superintelligence is viewed as a transformative event capable of solving fundamental human challenges, such as disease, poverty, and climate change.
Critics argue that this ideological framework can lead organizations to prioritize the acceleration of capabilities over rigorous risk mitigation. Proponents of rapid deployment, however, maintain that achieving advanced artificial intelligence safely is paramount and that maintaining a competitive edge is necessary to ensure these powerful technologies are developed by responsible democratic actors rather than adversarial states or poorly regulated entities.
Financial and market incentives also play a significant role. The commercial race to capture market share in enterprise automation drives companies to develop agents capable of performing complex, multi-day cognitive labor. Consequently, the commercial utility of autonomous agents directly conflicts with the cautious deployment strategies advocated by internal safety and alignment teams.
Policy Implications and Industry Responses
The public division among Anthropic engineers has renewed calls for external oversight and regulatory intervention. As frontier labs push the boundaries of agentic autonomy, policymakers in the United States and Europe are examining legislative frameworks to govern the development and testing of frontier models.
Industry reactions remain sharply divided. Some researchers and external computer scientists advocate for targeted boycotts of consumer-facing generative AI products to signal consumer dissatisfaction with current safety practices. Others argue that boycotts are ineffective and that the primary remedy lies in mandatory third-party safety audits, government-enforced testing standards for long-horizon agents, and legal accountability for systemic security failures.
The ongoing discourse highlights a profound governance challenge: how to manage the development of transformative technologies when the very scientists building them express uncertainty regarding their long-term control. As the debate moves from internal research forums to public platforms, the pressure on laboratory leadership to reconcile commercial ambitions with verifiable safety guarantees continues to mount.